Author Archives: admin

Agentic Engineering, part 3: Startup life

My newly minted sovereign server (sovereign in the sense that it answers to nobody, including me) had a horrible start in life. The PSU was faulty. In the picture, you can see my old 850W ATX PSU powering my new server (PSU on Marktplaats/Craigslist now). @Alternate is still trying to find out if it was really faulty. In the meantime, I ordered a second SFX PSU, which powers the server just fine.

Picture showing open server case with cables coming from external ATX PSU

First finding: It is a huge step up from the much pricier Synology. I re-used the after market 64GB DDR4 RAM and paired it up with a Ryzen 7 laptop CPU. Quieter snappy and in all things easier to use. Should have done this before. Switching has become a breeze as Claude knows every corner of the Open Source OS.

Agentic engineering – just like real work

After getting the tenant instantiation and the OAuth2 Entra integration ready, it was time to create some actual case management functionality. The first thing that struck me was that the carefully thought-out OAuth2-based authorisations for the key APIs we had also implemented were not working. Turns out Claude had skipped my API-first and “privacy/security by design” policies (authorisations need to be explicitly granted) and headed straight for the database to fetch cases for any visitor. Visitors were able to log in using the Entra integration and received access tokens and all the other trappings, but these were wholly ignored by the web app. When I begrudgingly told it to start using the APIs and OAuth2, it happily started minting its own tokens. It was clear: the context trap had closed on my efforts.

There was only one thing to do: Split the growing context into smaller projects and define clear boundaries. Like all boundaries, they need policing and careful architecting. My trusted QA agent happily handled that. Interestingly, this was where complexity really ramped up, and so did Token usage.

I split the app into four separate projects and redefined the scope for each agent working on it. The app is a case management system, and I am now in the process of completing the last nodes in the first demo process. So this week should not see such high token usage, as the node creation process is now well embedded in the other projects.

Lessons learned

  • Keep some spare parts around, it makes testing possible. Btw Claude’s assessment was 50% on the PSU and the next guess was at 23%, so a big help there.
  • Right to repair and the duty to try are well established in computer engineering. In this case the 64GB was also worth quite a bit of money. Again, Claude helped me find the motherboard I needed
  • Agentic engineering quickly becomes ‘Vibe coding’ when you are not paying close attention or are unfamiliar with software engineering.
  • I knew the context trap would hit me, and in which way I could avert it. However, I was too impatient to prevent it.
  • I am succeeding in Agentic Engineering, the result: a piece of software that might become truly useful and is regarded by some as quite complex.

Agentic Engineering, part 2: Immitating Intelligence

Three weeks after my first round of catch-up, two things have given out: my power supply and my patience with the word “agentic”.

First the easy part. I swapped the two Qwen 3.6 27b instances for Qwen3.8 27B, running the Unsloth Dynamic V3.0 GGUFs (UD-Q4_K_XL) with q8_0 KV cache quantisation on both Ollama instances, at 196k context. Unsloth uses a dynamic quantisation approach, worth a read.

Then I ran both cards flat out for extended periods. It turns out a be quiet! Straight Power 11 Platinum 850W is perfectly for two PowerColor R9700s in bursts, and much less happy when they are pinned for a longer stretch alongside a Ryzen 9 5900X. No bang, no smoke — just a distinct tic and a black screen of death. Ordered a Straight Power 12 Platinum 1200W at Alternate, mostly for the two native 12V-2×6 connectors. My earlier worries about hot feet and noise-cancelling headphones stand.

Which brings me to the actual point of this post.

The setup is the same as before: the two local Qwens do the typing, Claude does the thinking and the quality control. And Claude, the supposedly agentic bit at the top of the stack, keeps walking into walls that only a human with subject-matter knowledge can see coming. Not syntax errors. Not hallucinated libraries. Architectural road blocks, missing functionality (there is a user-management screen, please create the navigation to get to it from the management landing page) — the unreachable new page delivered with complete confidence.

[It’s a mystery to Fable 5 where the samples are]

My favourite example, because it is so beautifully wrong: at some point Claude decided we needed to prove ownership of the tenant’s domain, and proposed doing it the way every getting-started guide on the internet does it: drop a TXT record in DNS and wait for propagation.

Except that we had, together, in the same session, already set up an Entra OIDC integration. Which is to say: an app registration in the very tenant that owns that domain, issuing tokens for actual, named users authenticating against their IdP. The trust relationship was not only already established, it was established considerably more convincingly than a TXT record ever could. A DNS record proves that somebody, once, had write access to a zone file. An IdP federation with the tenant proves you are talking to the organisation and to its people, continuously.

Claude did not actively know that. Or rather, it knew both facts and never joined them up. Its algorithm correctly identified the need to “verify a domain”; unfortunately, it failed to understand it had already satisfied the requirement. Someone coined the phrase “imitating intelligence” and that is the best definition I have heard so far (from a podcast, forgot which one) for the seemingly incredible amount of knowledge the LLM’s have, but they can not be relied upon to connect all the dots.

And this is where I get slightly cranky about the Agentic claim. We have gone from Vibe-coding to Agentic Engineering in about a year, and the second term is meant to signal that the machine now has agency: it plans, it decides, it executes. What I actually have on my desk is a very fast, very well-read team of juniors who produces more code before lunch than I do in a month, and who will confidently take a wrong architectural turn, forget about its audience, or implement completely useless functionality.

Learning points

  • Agentic engineering does not remove the need for deep understanding of the tech being used. I made my orchestration agent quite chatty, and the questions it asks usually have deep repercussions for the usability and maintainability of the system.
  • Model quality is not the bottleneck any more. Qwen3.8 writes fine code. The bottleneck is that nothing in the stack holds the architectural intent between steps.
  • Sustained load is a different beast from benchmark load. Size your PSU for the hour, not for the demo. 850W was plenty right up until the tic.
  • The failures that cost you money are not the ones that throw errors. Broken code announces itself; a redundant-but-working design decision quietly lives on for years.
  • Write documentation, and re-write it. I have installed Docmost (wiki) and Plane (backlog/project management) and have a specific agent skill for (re-)writing all documentation. I spent about 40 hours with Claude creating the architectural and functional documentation before any code was written. This sounds limited and it is, because I already did the work for this project and still it took 40 hours to write it down again.

Next steps

The 1200W supply goes in today, together with a second NVMe so the models stop fighting my boot drive for space (which, delightfully, means pulling a GPU to reach the M.2 slot — whoever designs these layouts owes me a beer).

Btw, if you need someone to lead your developers — be it human or AI — in delivering custom applications: I am available for a new assignment.

Agentic Engineering using local LLM’s (yes plural)

Apparently, the lingo has shifted; having code generated by LLM’s is no longer to be called Vibe-coding, but Agentic Engineering. Being left behind in the past months by great token slayers agentic engineers like @PatrikHusfloen is something my ego can’t take for too long. Wrongs have to be righted.

Thus, starting yesterday, I have committed to play some catch-up. The first problem is that I have to pay for my own tokens and do not get sponsorship from Agentic Engineering boosters such as @ErikHietkamp. However, you might remember I bought two 32GB VRAM cards, which means I can run two instances of Qwen 3.6 27b (the dense model which beats the MoE 35b at coding by a comfortable margin) using Ollama.

The Qwen 3.6 is roughly equivalent to Opus 4.5 and actually beats it on Agentic Terminal Coding.

Of course, the current top models score a lot higher and these two LLM’s could use the higher quality guidance and quality control. To achieve this, I connected the models to Claud using the ‘Rawveg/Ollama MCP’ server. There was a small bug whose pull request has not yet been merged, so I had to do some old-school programming to fix it (yes, it was that minor).

Now the only problems remaining are that my feet will get pretty hot and I need some noise-cancelling headphones.

How I Vibe-Coded a Working Meeting Booker in One hour

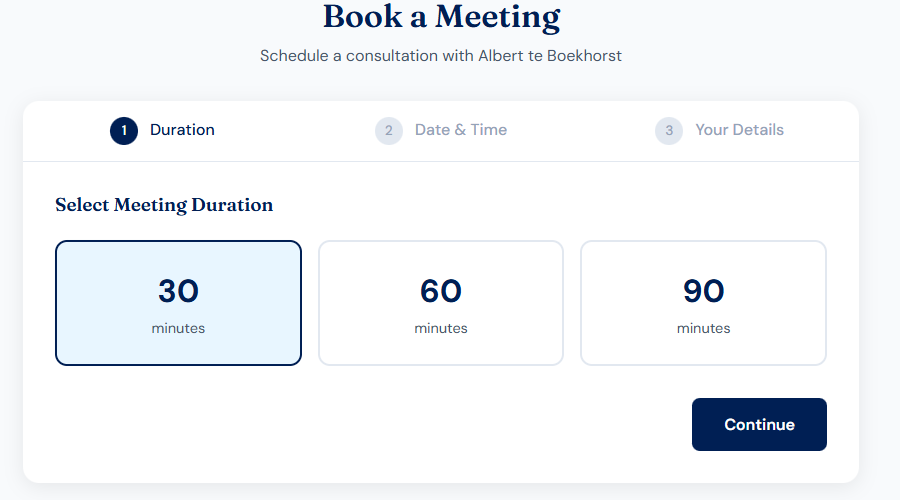
TL;DR Book a Meeting | Blue Sky Consulting

It was time to re-jump on the Vibe coding bandwagon again. I fell off somewhere two years ago, when I was between jobs. In that period, AI was relatively new, and I created an API that took a humble CSV file from the HomeWizard app and calculated what my electricity bill would look like with an hourly changing rate. For me, it was a great success. ChatGPT successfully created an Azure function that listened to https requests. It successfully opened and read the CSV file and only stumbled on the actual algorithm (which I was able to fix in 5 minutes. The entire thing took about 15 minutes, which I would have taken a lot longer with all the cruft that had to be handled. I wanted to create a website around that API, and AI failed to get that up and running in any meaning full time.

Fast forward: 2-years later in 2026. Claud opus 4.5 was the new kid on the block. I asked it to create a website for my own consulting firm: Blue Sky Consulting. It went a bit overboard with some bold claims (perhaps it was trained a bit too much on American content) that might be too out of touch with reality; however, it was/is an acceptable site. I published it as is (except for some bold claims that is) without putting too much effort into fixing some minor issues (the tiny home button is still cracking me up), and proceeded with some actual functionality: The Book a Meeting button.

Booking a meeting/lunch, drinks, I love VAR t-shirt giving ceremonies, re-connect, whatever meeting option (yes, please use it if you read this and haven’t spoken to me for a while Book a Meeting | Blue Sky Consulting), is something everyone should have on their professional site. It is actually connected to my Outlook through Microsoft Graph and sends emails using contact@blueskyconsult.nl to verify would-be-bookers’ email addresses to prevent the bot army prowling the internet to book meetings (which so far seems to be working well enough). It shows you open slots in my calendar to choose from. When the authenticity of the mail address is confirmed, it books a meeting with a MSFT-teams link and sends out the invites.

The only bug was with date-time offsets between my server and MSFT Graph; it took a few debug rounds to fix it, but it did a most acceptable job. I had a similar experience with a sync tool Claud created for me to sync my customers’ Outlook calendar with my Blue Sky Consulting calendar.

My biggest takeaway is that it would be really beneficial to set up some automation in the testing that gives feedback to Claud. Next up is fixing an old and broken-down app: mappingtrust.com. Which should be interesting, as it has enough data in there to create some actual strong test cases.

The Hidden Crisis: Who Teaches AI After Stack Overflow?

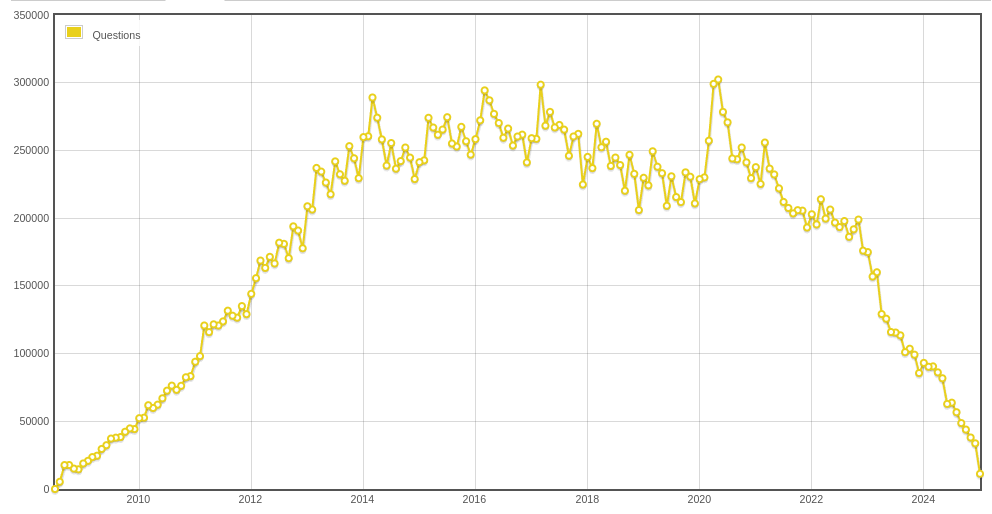
About a year ago there was a post about the demise of StackOverflow, the portal used by many techies for solving common (and not so common) issues that arise with the use of technology. n00bs and experts all mixed together with the common goal of solving issues resulting from gaps in (unread) documentation. The platform was already in decline from 2018 onwards, with a nice COVID resurgence, and the launch of ChatGPT resulted in a swift drop to almost zero:

The reason is simple: LLMs give answers in your context, where in the past I needed a number of StackOverflow posts, some blogposts, and the product’s own documentation to solve my issues. LLMs combine all this information for me and spit out good enough answers to make me solve the issues I face. The LLMs are an enormous time and energy saver. However, the future AI can not make use of the content from StackOverflow as the generation of that content has virtually stopped.

I suggested that better documentation, written by the same tools that finished off StackOverflow, might fill the hole of content creation and teach future LLMs how to solve problems. Now, hope is not a strategy and thus, I went on a fact-finding mission. I run about 45 Docker containers divided in about 30 stacks on my home server. I dislike writing documentation just as much as the next person, so I never bothered to document any of it. How nice would it be to have an LLM write it for me?

Recently, I have subscribed to Claude.ai and they have an integration with Chrome/Edge that might do the trick. So I navigated to my DocMost wiki and fed it my infrastructure Docker Compose files (think reverse proxy, IAM, Redis, DB’s etc.). In no time it spit out some descriptions of the stack. Nothing too fancy okayish content. However, when I asked it to create a Mermaid diagram is when I saw the real magic happen. It really understood how everything worked together and created a fine diagram.

As it looked really promising I then asked it to generate some content around individual Docker stacks, and list dependencies, and how to reach the actual apps. It again created beautiful mermaid context diagrams, showing how it worked together with other Docker containers. It horribly, struggled when I asked it to create links under the addresses where apps were reachable. It completely died on me when I asked it to create a summary of all the used ports on the Docker host in one table. As the generation slowed down, I tried spinning up a second instance and have two session generating content, but the second one gave up a lot faster than number one. It was just not as dedicated and determined as the first one, and quite frankly, highly disappointing.

Learning points

  • Claude was not strong in determining what is important to document, I had to direct it on what to focus on.
  • Diagramming using code was always my favorite, and obviously, Claude feels the same way. The Mermaid diagrams were brilliantly done.
  • Accessibility for non-MCP interfaces is really important (DocMost fails in that regard), Claude for Chrome/Edge was burning through tokens (usage limits) faster than I have ever seen it do before (I use the Max plan), and still failed to select text in a table to add a simple hyperlink. It was generating and analyzing screenshot after screenshot, trying to select text and add rows to existing tables.

Conclusion
My experience in solving issues using LLMs that arise from using :latest versions (and auto updating using Watchtower) is that I find myself consulting release notes again. This is where LLMs can really help with writing comprehensive documentation, but not without proper supervision. I think, therefore, there is still some space for a StackOverflow type site, but expect little ‘in-person’ views and lots of LLM/agents looking around to find answers to questions. The big question is going to be: What will be the business model that will float these websites? As the eyeballs of consumers are unlikely to return …

Next steps:

Install Notion as a Wiki, it has native MCP, and thus should be much easier for Claude to communicate with.

Secure Document Automation Made Simple: Ollama + N8N

As it feels like everybody has jumped on the local AI bandwagon by now, I felt a bit left behind. So it was time to dip my toes in the water and avoid my year-end admin chores. Of which the most mind-numbing is figuring out the tax mess, which in the Netherlands is almost entirely a snail-mail affair (yes, Dutchies, I am talking about business taxes). The amount of blue envelopes shipped to my home address is staggering and messy. A classic ‘unstructured data’ problem ripe for the plucking with the current state of local AI. It’s time to sort things out using some local LLMs and N8N to keep things private, secure, and as digital as possible.

First things first: I bought a Canon scanner (MF657CdW) with the ability to scan documents double-sided and store them fully OCR’ed on disk or cloud. Next step: add some RAM to my 5-year-old Desktop so it will happily run gpt-oss:120b. Update some broken Docker containers and finally determine why my port forwarding never worked (it sent the replies through my VPN). Port forwarding had to work to get OAuth flows running in N8N; the next blocker was my Authelia IAM, which needed some exceptions for call-backs to N8N.

Selecting the platform for running LLMs was easy: Ollama, as it had the option of opening up the LLM through an API. Installing N8N for agent/workflow tasks was also pretty simple (as I already had Postgres and Redis installed). Creating the workflow and connecting all the steps was a breeze. I successfully mailed my bookkeeper and uploaded the documents to their respective folders and bookkeeping software where necessary.

Lessons learned:

  • N8N has some strange quirks around Oauth setup, first create the credential, and if the connection fails, try again via ‘in-private browsing’
  • Filename changes when uploading documents are ignored, but using a bit of code to change the filename of the binary before uploading does work … Must be a n00b thing, don’t hesitate to give pointers.
  • Let the LLM worry about its own shortcomings by feeding it its excrements and referring to the previously given spec. It took about 5 iterations before it created a verbose enough prompt that survived all the content (yes, even the butterfly my daughter drew for me, which ended up in the snail mail stack).
  • Old hardware is still good enough for some fun, and when buying new, never skimp out on specs, especially RAM.

Next steps:

  1. When the document is a receipt or invoice, create a mutation in the right category in e-boekhouden.nl.
  2. Identify any actions and create Vikunja (my todo-list) tasks for them.
  3. Add all the data to a RAG DB in the hope the LLMs will get clever enough to actually help me optimize my tax strategies in the future (no, we’re not there yet). For now, I will hire Marieke for that.

But first: buy a lot more VRAM to speed up the larger models (8 tokens/s for gpt-oss:120b). When running in the background, this is an acceptable speed, but when debugging, I need things to run a lot faster.

Unraveling the Agile Myth: Does It Truly Deliver More Value?

Recently, I came across a post claiming that agile projects were nearly 1.5 times more successful. This headline seemed too good to be true, and indeed it was. The claim was based on a survey posted on X and some LinkedIn groups. While the survey is well-documented and certainly worth a read, there was no formal definition of how to measure success, and the definition was left to be determined by the individual (and self-selected) participants. Another issue with this study was the ways in which success was measured: “On Schedule,” “On Budget,” and “To Specification”. Considering Agile aims to generate value and Waterfall is usually measured against a business case, it is strange to measure success based on these criteria alone. Thus, I found little support for the premise posted in the post and asked if anyone could share more solid research on the subject. Suddenly, the dragons were gone, replaced by crickets…

Believing there should be something out there that proves Agile is a success, I started my search:

I found “Agile versus Waterfall Project Management:
Decision Model for Selecting the Appropriate Approach to a Project
” which I expected to hit the bullseye, as making a selection should be based on solid studies showing which factors would make Agile successful over the Waterfall approach. Unfortunately, the authors probably faced the same issue I am encountering: The research showing the success of Agile is hard to find. So, they did the next best thing and interviewed 15 project management experts (yes, I know) and set up a survey to corroborate the experts’ opinions. The selection criteria are categorized in “project constraints” and “people and culture,” and phrased in a way that a ‘higher’ score points towards Waterfall. It felt a bit biased to me, and there were no hints (besides the experts’ opinions) of any proof that one approach might be better than the other. In addition, the criteria cannot be scored objectively. Also, one of their reasons for not choosing Agile is disproved in the following paper.

Does Agile work?-A quantitative analysis of agile project success is a nice read. The paragraph (2.2) on project succes is the best one from the studies I found so far and the moderator variables on project succes (2.3) (alignment of project with organization goals, project complexity and experience level of the team) seem strong summaries of the available literature on these subjects. This study concludes that there is a small, but significant, correlation between the application of agile principles in projects and project success. However the results might be somewhat depressed as the survey was conducted among members of PMI or LinkedIn project management groups. This might also explain why the measured up-front planning for agile initiatives was found to be similar to their less agile counterparts (you still need some, but not as much up-front planning; feel free to contact me for a design and discovery sprint to get your agile initiative started on the right foot). Another interesting conclusion is on project complexity not being a moderator on Agile project succes (in contrast with what the paper on the decision model above would like you to believe).

A Survey Study of Critical Success Factors in Agile Software Projects is a bit of dated work (e.g., Extreme Programming is over twice the size of Scrum), but it’s an interesting study as it focuses on what makes Agile successful. Paragraph 4.5 is an interesting read as it links the factors evaluated to the Agile Manifesto and identifies the overlaps and gaps alike.

All in all, I am still not impressed by the proof available in the scientific literature supporting the premise of Agile delivering more value. Although I found one study showing a significant improvement one swallow does not make a summer. So, if you know of any studies out there delving into this subject, please share them in the comments.

Agile performance – Are we doing well?

Are we doing Agile well? Answering this question seems to be top of mind. However, the solutions proposed are not always that Agile from the outset. Recently I received a piece of thought ware on this subject that was less then Agile in my humble opinion. It wanted to answer the question ‘Are we doing Agile well?’ by measuring:

  • Velocity Variance (Lower is better)
  • Story points committed vs delivered
  • Sprint predictability

From my first impression, these metrics seem to be measuring a number of totally incoherent dimensions like Holiday seasons (velocity variance anyone?), lack of team ambition, sickness, etc. Focusing on these dimensions seems to be counterproductive. Any sane team being judged on these metrics would reduce their velocity to a point where variance becomes zero, avoid innovation and risks and all story points will be delivered and sprints become 100% predictable. The speed where these metrics are optimal is probably somewhere well below the optimum output of the team in question and thus results in wasted resources.

From my experience, any ‘performance metric’ based on story points is flawed as it will hurt performance or impede the actual value story points and velocity provide: aid in planning Agile development in the short and intermediate-term and help predict ROI. Using story points as a performance metric usually results in either ‘story point inflation’ or wasted resources.

The best way to get teams to perform and reach your goals is by measuring the value delivered. Of course, measuring this is hard (btw it shouldn’t be), but when you succeed it will pay off handsomely. It focuses all team members on maximizing the bottom line. This will result in the team stepping up to take ownership of the goals of your organization and huge leaps forward in effectiveness. It does open up the vulnerability of short term gains in favor of long term sustainability, but this is remedied by making sure your teams contain members with a long term commitment to your operations.

So which ‘metrics,’ other than value delivered, could an outsider use to determine how teams are performing or where you could help them improve?

  • Burndown. Does it follow the ideal path? Or is it a steep drop on the last day of the sprint?
  • Overhead in preparing stories and time spent in poker sessions. In my experience, these vary a lot.
  • Participation and contribution of each single team member.
  • How many innovative ideas do the teams generate to increase their effectiveness? (whether implemented or not)
  • Impediments – are they reported? Or is everybody accepting the status quo?

Please share your thoughts and experiences on the topic in the comment section below.

MBA: Confirmation of Graduation

Dear Mr. Boekhorst,

The Examination Board met on Tuesday 16 February 2016 to review the academic performance of EMBA15 participants.

We are pleased to inform you that your grades have been ratified by the Board and that you have met all the academic criteria required for the award of Masters in Business Administration.

We look forward to greeting you at the formal graduation ceremony on Friday 18 March 2016 where you will receive your diploma and graduation transcript.  Please note that the graduation ceremony is the day you officially graduate and accordingly may use the degree and title conferred. For this reason we are not able to supply official transcripts or diplomas before that date.  We will be providing you with the class ranking band soon after the graduation.

With kind regards,

RSM


Category: MBA

MBA experiences: In class simulations

One of the most exhilarating activities during the MBA was the in-class simulations. The direct head-to-head challenges either between teams or individuals are very exciting, and enjoyable if you are an adrenaline junkie. During the RSM EMBA, we only had three instances where we were graded on these simulation sessions.
Sonite Sales
The first was the Markstrat marketing simulation game. A game where we competed in teams against each other for the favor of the virtual customers. Our team’s strategy, to dominate the low-end market segment by “selling a ****load of Sonites” to the growing customer segments of Shoppers and Savers, worked out brilliantly. In a later stadium, our team also succeeded in taking >50% of the market value share of the “professional” customer segment. The blue line shows how our team’s strategy dominated the market in terms of sales volume.

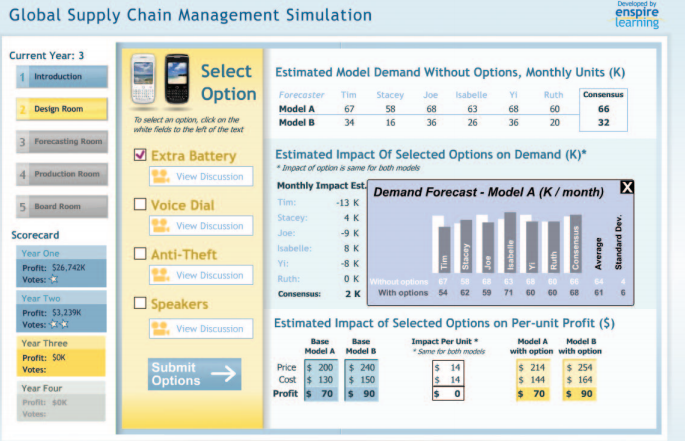
Supply chain simulationThe second graded simulation was the global supply chain management simulation. It was an individual effort where my ego got hurt by Pedro Iriondo who took the first place ahead of me. However, the combination of Board questions and rapid fluctuations in customer demand and product options made the simulation an intense and fun exam even when losing.

ExperienceChange model[1] The third simulation was part of the course “Leading Strategic Business Change” and was called ExperienceChange. In this intense simulation, I had the honor of leading the best team (out of 16). Important success factors were the structured and efficient preparations that enabled us to go for a nice walk around campus between the prep session and the actual simulation.

How to prepare for these events? Play a lot of RTS games. A gamer’s mindset is not only useful when engaging customers, it also trains skills in information processing, resource allocation, and decision making. In addition, it helps to have experience in programming as I found a bug in the Markstrat simulation that gave me a minor tactical advantage over the competition. Of course, I reported the bug and how it could be reproduced in full accordance with the student code of conduct (it should be fixed by now).